Genrius AI
Generating Real Intelligence. We build AI models and make them small and fast enough to run on hardware people already own.
Pingala-8: 2-bit LLMs for llama.cpp, no retraining
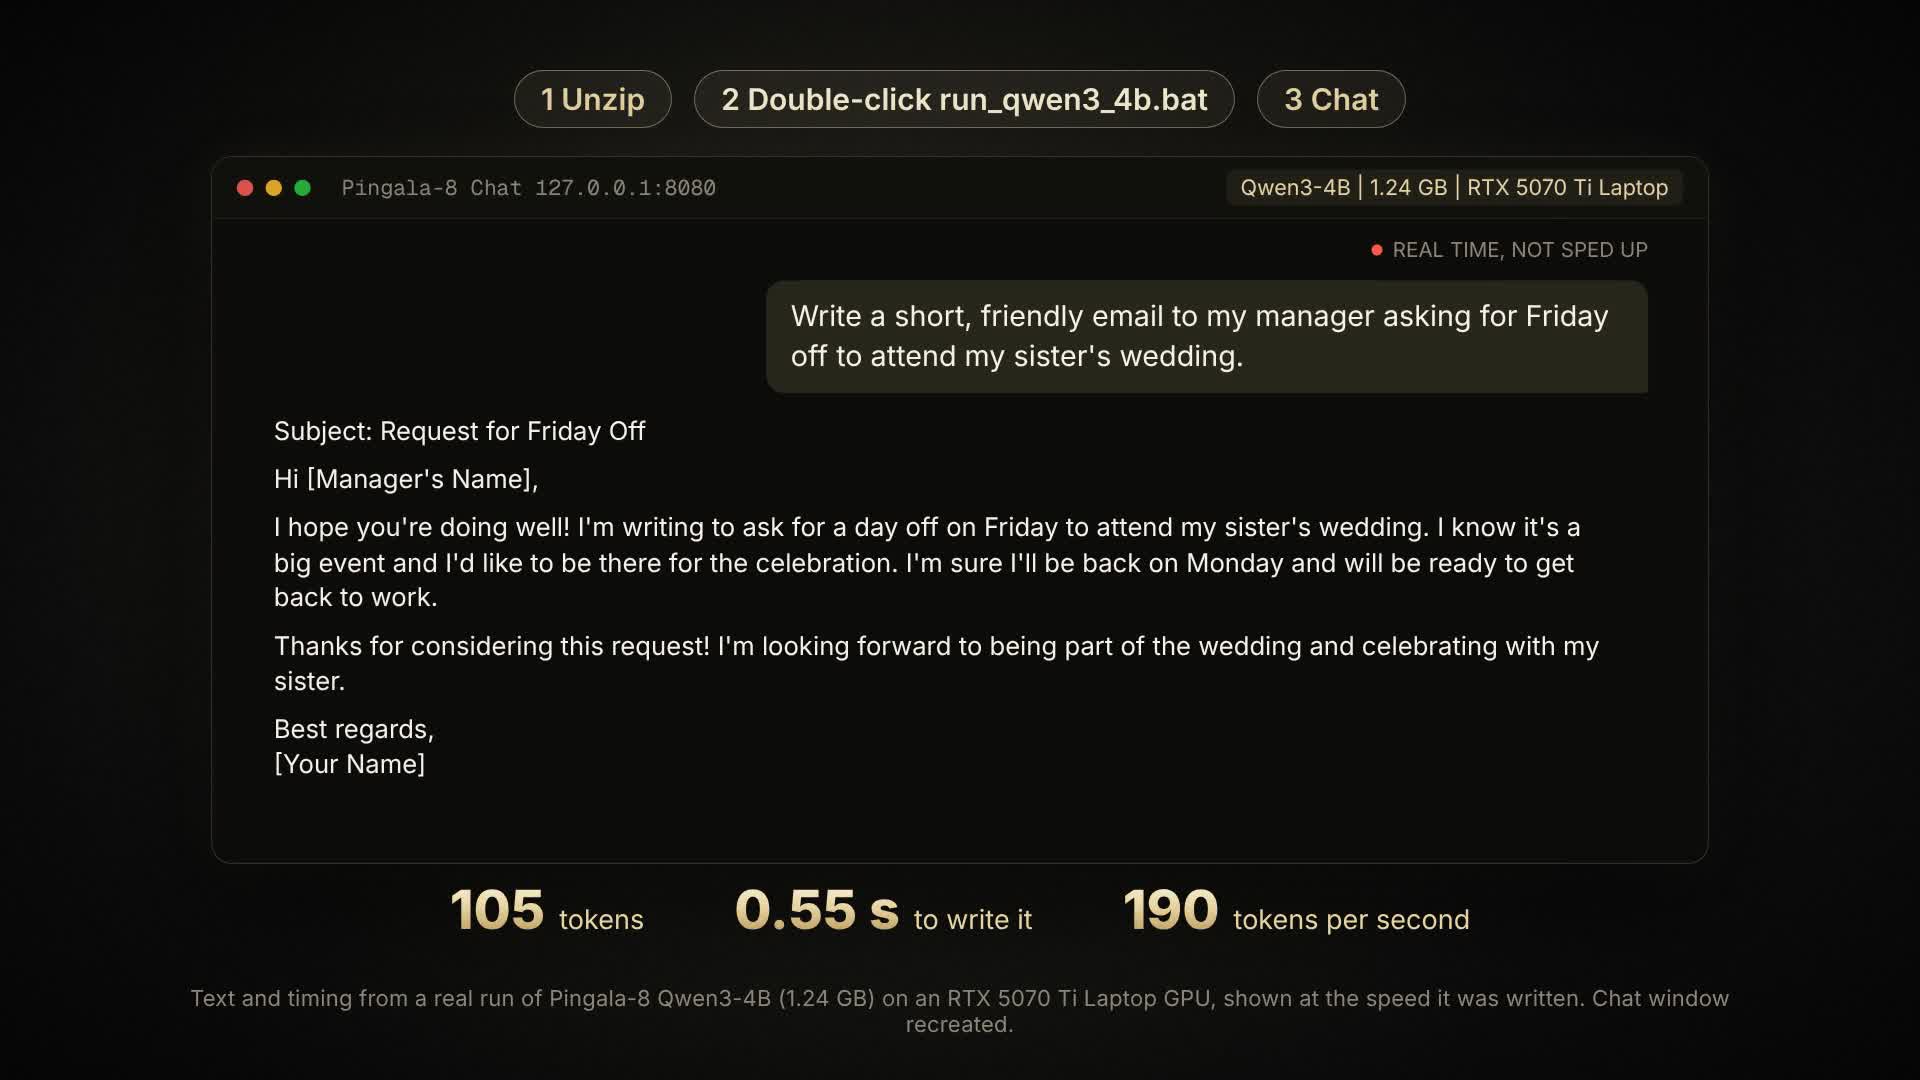
- 85% smaller: Qwen3-4B goes from 8.05 GB to 1.24 GB, and Llama 3.1 8B from 16.08 GB to 2.39 GB.
- At the file size of llama.cpp's IQ2_XXS, our Qwen3-4B reaches WikiText-2 perplexity 16.64. IQ2_XXS reaches 28.61 and the best IQ2_KT file we built reaches 18.15 (lower is better).
- Where we lose: Qwen3-14B (IQ2_KT 9.40, ours 9.57), prompt processing (0.74x of IQ2_XXS), and retrained models such as Ternary Bonsai 4B.